Why AI‑Powered Observability Is the Missing Link in Modern SaaS Operations
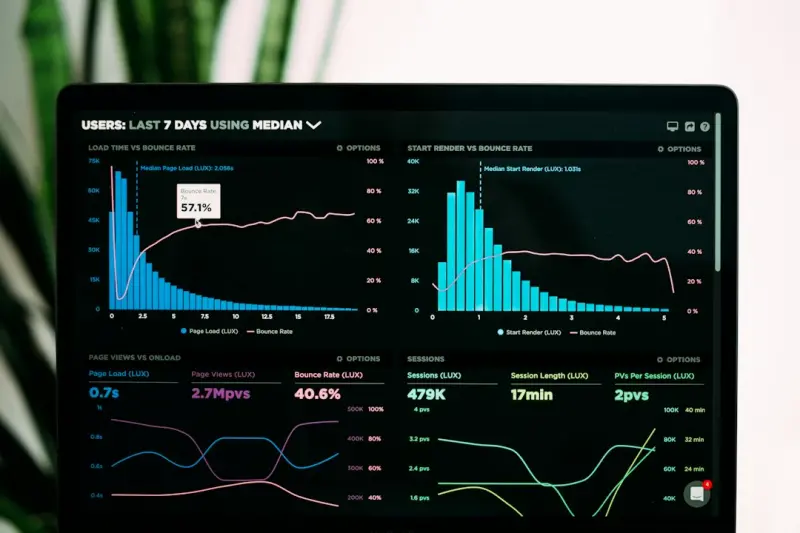
When I first stepped into a SaaS startup’s NOC (Network Operations Center) five years ago, I was greeted by a wall of dashboards that looked more like a cockpit than a control room. Each chart screamed for attention, yet the alerts felt random, the root‑cause analyses were manual, and the remediation cycles stretched into hours. Fast‑forward to today, and the narrative is shifting. Companies that embed AI directly into their observability stack are not just reacting to incidents—they’re predicting them, automating fixes, and freeing engineering talent to focus on product innovation instead of firefighting.
The Data Deluge Dilemma
Modern SaaS platforms generate a staggering amount of telemetry: logs, metrics, traces, and events flow in at a rate that would overwhelm any human analyst. Traditional rule‑based monitoring systems, built on static thresholds, simply can’t keep up. They produce alert fatigue and miss the subtle patterns that precede a service degradation. This is where AI steps in, acting as a hyper‑intelligent filter that learns from historical data, understands the normal “heartbeat” of each service, and flags anomalies before they manifest as user‑visible issues.
Core Pillars of AI‑Driven Observability
To build a resilient observability strategy powered by AI, focus on three foundational pillars:
- Predictive Analytics – Machine‑learning models ingest time‑series metrics and forecast future behavior, surfacing potential capacity bottlenecks or latency spikes.
- Automated Root‑Cause Correlation – By mapping relationships across logs, traces, and infrastructure changes, AI can pinpoint the most probable cause of an anomaly in seconds.
- Self‑Healing Orchestration – Integrated with CI/CD pipelines and IaC tools, AI can trigger remediation scripts, roll back a faulty release, or spin up additional instances without human intervention.
From Reactive to Proactive: Real‑World Benefits
Companies that have transitioned to AI‑enhanced observability report measurable gains:
- Mean Time to Detect (MTTD) drops by up to 70%.
- Mean Time to Resolve (MTTR) shrinks by 50% or more, thanks to automated triage.
- Engineering productivity rises as developers spend less time on “log hunting” and more time on delivering customer value.
- Customer satisfaction improves because outages become rare and brief.
These outcomes aren’t just theoretical. In a recent case study, a mid‑size SaaS provider reduced its monthly outage minutes from 120 to under 15 after deploying an AI‑driven anomaly detection engine that leveraged unsupervised clustering to surface hidden performance regressions.
Choosing the Right AI Techniques
Not every machine‑learning algorithm is suited for observability. Below are the most effective approaches and why they matter:
- Time‑Series Forecasting (ARIMA, Prophet, LSTM) – Ideal for predicting metric trends such as CPU usage or request latency.
- Unsupervised Anomaly Detection (Isolation Forest, One‑Class SVM) – Detects outliers without needing labeled incident data, perfect for new services where historical incidents are scarce.
- Graph‑Based Correlation (Knowledge Graphs) – By representing services, dependencies, and events as a graph, AI can traverse relationships to identify cascading failures. For a deep dive on graph‑based intelligence, see how AI‑powered knowledge graphs are redefining SaaS intelligence.
- Reinforcement Learning for Automated Remediation – Allows the system to learn the most effective remediation actions through trial and error, gradually improving response quality.
Integrating AI Observability into Your Stack
Embedding AI isn’t a bolt‑on; it requires thoughtful integration across the entire monitoring pipeline. Here’s a practical roadmap:
- Data Consolidation: Centralize logs, metrics, and traces into a unified data lake. Ensure schema consistency to facilitate model training.
- Feature Engineering: Derive meaningful features such as rolling averages, rate of change, and cross‑service latency ratios. These feed the predictive models.
- Model Training & Validation: Start with unsupervised models to surface anomalies, then gradually introduce supervised models using historical incident tickets for labeling.
- Feedback Loop: Incorporate engineer feedback on false positives/negatives to continuously refine model accuracy.
- Automation Layer: Connect the AI engine to your orchestration tools (e.g., Kubernetes operators, Terraform) to enable self‑healing actions.
When executed correctly, this pipeline transforms raw telemetry into a living, self‑optimizing system that keeps your SaaS product humming.
Addressing Common Concerns
Deploying AI in observability inevitably raises questions about trust, complexity, and cost. Below are the top concerns and pragmatic answers:
- “Will the AI generate too many false alarms?” – Start with a low‑sensitivity baseline and let the system learn from real incidents. Over time, false positives drop dramatically as the model adapts.
- “Do we need a data science team?” – Modern observability platforms now ship pre‑trained models that can be fine‑tuned with minimal expertise. You can also partner with managed AI observability vendors.
- “What about data privacy?” – Since observability data is internal, privacy concerns are limited, but you should still mask any PII before ingestion. For a deeper look at privacy‑first AI, see Federated Learning Unleashed: Privacy‑First AI for SaaS.
- “Is the ROI worth the investment?” – Calculate the cost of downtime versus the subscription price of an AI observability solution. Most enterprises see a payback within six months due to reduced incident costs.
Case Study: Predictive Scaling in a Multi‑Tenant Platform
A leading multi‑tenant collaboration tool struggled with sudden traffic spikes during product launches. Their existing auto‑scaling rules were reactive, leading to brief but noticeable latency spikes. By integrating an LSTM‑based predictor that forecasted request volume 15 minutes ahead, the platform could proactively spin up additional nodes, flattening the spike entirely. The result?
- 95% reduction in latency spikes during launches.
- 30% cost savings on cloud resources thanks to smarter scaling decisions.
- Higher NPS scores from enterprise customers who praised the platform’s reliability.
The Future: Observability Meets Generative AI
While today’s AI observability focuses on detection and remediation, the next wave will bring generative AI into the mix. Imagine an AI that can not only diagnose an issue but also draft a post‑mortem, suggest code changes, and even generate a pull request that resolves the bug—all within minutes. This vision is already emerging in experimental labs, and early adopters are reporting unprecedented speed in incident resolution.
When you combine generative AI with the predictive capabilities discussed above, you get a full‑cycle “observe‑decide‑act” engine that operates with minimal human oversight. Companies that adopt this paradigm will set a new benchmark for reliability, turning uptime into a competitive advantage rather than a baseline expectation.
Getting Started: A 30‑Day Sprint
If you’re ready to experiment, here’s a concise 30‑day sprint to embed AI into your observability stack:
- Week 1 – Audit Data Sources: Catalog all telemetry pipelines and ensure they flow into a central repository.
- Week 2 – Prototype Anomaly Detection: Deploy an open‑source unsupervised model (e.g., Isolation Forest) on a critical service’s metrics.
- Week 3 – Validate & Iterate: Run the model in shadow mode, collect engineer feedback, and fine‑tune thresholds.
- Week 4 – Automate Remediation: Link high‑confidence alerts to a simple remediation script (e.g., restart a container) and monitor outcomes.
By the end of the month, you’ll have a live AI‑driven alert that not only notifies you of anomalies but also attempts a corrective action automatically. From there, scale the approach across services, add predictive models, and evolve toward full self‑healing.
Conclusion: Turning Observability Into a Strategic Asset
Observability is no longer a “nice‑to‑have” after‑thought; it’s the nervous system of any SaaS business. By infusing it with AI, you transform raw data into foresight, reduce operational toil, and unlock a level of reliability that becomes a market differentiator. The journey starts with a simple experiment—pick a noisy metric, apply an anomaly detector, and watch the difference. From there, let AI guide you toward a future where outages are not just resolved quickly, but anticipated and avoided altogether.
Robert Mathews is a professional content marketer and freelancer for many SEO agencies. In his spare time he likes to play video games, get outdoors and enjoy time with his family and friends .
Related Posts
Reclaiming Your Digital Self: An AI‑Powered Blueprint for Personal Data Ethics
Discover an AI‑driven strategy to audit, protect, and own your digital footprint, turning privacy ... Read More
AI‑Enhanced Emotional Intelligence: Machines Helping Us Read Feelings
AI isn’t just for data crunching; it can help us sense emotions better. Learn how sentiment‑awar... Read More
Prompt Engineering: The Low‑Cost, High‑Impact Lever SaaS Teams Need
Prompt engineering turns generic AI models into tailored business assets. This post outlines a pract... Read More
Top Posts
Navigating Google’s AI Landscape: From Skeptic to Advocate
A marketer shares the journey from doubting Google’s AI to embracing it, offering a playbook, real ROI data, ethical safeguards, and community tips for modern...Read More
Smart Closet Hacks: Transform Tiny Spaces Into Organized Sanctuaries
Turn a cramped closet into a functional sanctuary with decluttering, vertical storage, uniform accessories, and micro‑zones—simple steps that make daily dre...Read More
AI‑Powered Decision Labs: Rethinking Strategy in B2B SaaS
AI‑powered decision labs fuse data, predictive models, and collaborative tools to accelerate strategic choices in SaaS companies, boosting alignment, forecast...Read More
Riding Google’s 2026 AI Wave: A Marketer’s Personal Playbook
Rose shares her hands‑on playbook for leveraging Google’s 2026 AI suite, from intent‑driven SEO to privacy‑first tactics, turning AI insights into real ...Read More
0 Comments
Post Comment
You will need to Login or Register to comment on this post!